CARL: CUDA-Accelerated Rocket League
This post introduces CARL, a GPU-resident Rocket League simulator built for reinforcement learning. Inspired by the likes of IsaacLab [1] and PureJaxRL [2], CARL’s parallel environment enables the rapid training of Rocket League agents. Many thousands of games can be run simultaneously on a single GPU, which exposes the policy to significantly more experience in less time than serial simulations. Credit goes to RocketSim [3] and the Bullet physics engine [4] for the ported logic.
Benchmarks
PPO was run on both CARL and RocketSim to evaluate training throughput. Benchmark runs were configured such that the same number of gradient updates were applied over the course of 1M decision steps. This was done by inversely scaling the rollout length by the number of envs while keeping all other parameters the same between runs with the two frameworks in question.
Given that this benchmark includes policy forward/backward, critic forward/backward, data transfer overhead, advantage estimates, and so on, we are able to paint a complete picture of the benefits of leveraging CARL on real-world training workloads.
| Framework | # Envs | Time (s) | Throughput (transitions/s) |
|---|---|---|---|
| RocketSim | 1 | 475.90 ± 38.55 | 2,145 ± 159 |
| RocketSim | 4 | 385.78 ± 2.66 | 2,633 ± 18 |
| RocketSim | 8 | 326.03 ± 4.76 | 3,116 ± 45 |
| RocketSim | 16 | 286.84 ± 2.16 | 3,542 ± 27 |
| CARL | 256 | 15.11 ± 0.41 | 67,280 ± 1,830 |
| CARL | 1,024 | 6.77 ± 0.20 | 150,106 ± 4,334 |
| CARL | 2,048 | 4.53 ± 0.19 | 224,567 ± 8,963 |
| CARL | 4,096 | 3.72 ± 0.24 | 273,635 ± 16,379 |
Benchmark code: carl-benchmarks
Benchmark Hyperparameters
| Parameter | Value |
|---|---|
| Algorithm | PPO |
| Total timesteps | 1M |
| Epochs | 10 |
| Minibatch size | 32,768 |
| Total batch size | 32,768 |
| Frameskip | 4 |
| Max ticks per episode | 36,000 |
Using CARL as our environment framework, we achieve a 77x decrease in the time per transition during training. Predictably, throughput scales with the number of parallel environments.
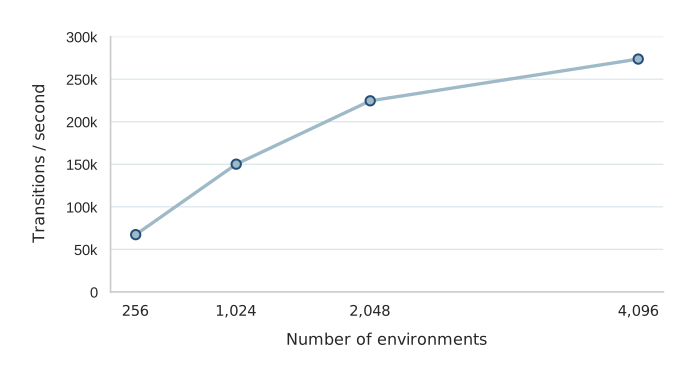
Benchmarks were run on an Intel Core i5-13600K CPU, NVIDIA GeForce RTX 3060 GPU with 12 GiB VRAM, and 32 GiB RAM. GPUs with more SMs, Tensor Cores, etc. would open us up to greater throughput depending on the learning algorithm. VRAM, however, is not the simulation bottleneck, and at reasonable rollouts the observation buffer fits comfortably on the GPU at just a couple hundred MB. The simulation itself allocates just over 20 MB for 4,096 envs.
Interface
CARL exposes the underlying simulation via the standard Gymnasium API. It is planned to add support for other ML libraries like JAX and TensorFlow, but the default wrapper at the moment is written in PyTorch. As with all other Gymnasium-wrapped environments, one need only initialize, reset, and step!
import torch
from carl.gymnasium import CARLTorchVectorEnv

env = CARLTorchVectorEnv(n_sim=8192)

observation = env.reset()

actions = torch.zeros(
    env.action_space.shape,
    dtype=torch.float32,
    device=env.device
)

observation, reward, terminated, truncated, info = env.step(actions)
Action Space
Internally, CARL represents actions with shape $(n_{\mathrm{sim}}, n_{\mathrm{cars}}, 7)$, though users may treat each car as its own “environment”, where actions are submitted in the shape $(n_{\mathrm{sim}} * n_{\mathrm{cars}}, 7)$.
Actions by default are continuous, though the user can specify discrete actions via discrete_actions=True. In that case, the maximum continuous action is applied.
Action controls
| Action | Continuous | Discrete | Effect |
|---|---|---|---|
| Horizontal | $[-1, 1]$ | $0, 1, 2$ | Steer on the ground and yaw in the air |
| Vertical | $[-1, 1]$ | $0, 1, 2$ | Pitch the car up or down |
| Throttle | $[-1, 1]$ | $0, 1, 2$ | Drive forward or reverse |
| Powerslide | $[0, 1]$ | $0, 1$ | Hold to drift and turn sharply |
| Boost | $[0, 1]$ | $0, 1$ | Hold to consume boost for acceleration |
| Air roll | $[-1, 1]$ | $0, 1, 2$ | Roll the car while airborne |
| Jump | $[0, 1]$ | $0, 1$ | Jump from the ground or dodge in the air |
Actions are held for every tick over the subsequent frameskip ticks.
Observation Space
The observation space has shape $(n_{\mathrm{sim}} * n_{\mathrm{cars}}, d_{\mathrm{obs}})$, where each float32 row describes one car’s view of the game. Internally, CARL groups observations as $(n_{\mathrm{sim}}, n_{\mathrm{cars}}, d_{\mathrm{obs}})$. CARLObservation provides convenient named tensor views over these contiguous blocks.
Observation features
| Block | Contents |
|---|---|
| Ball | Position, linear velocity, and angular velocity |
| Cars | Position, velocity, angular velocity, orientation, boost, and state flags |
| Boost pads | Active state and distance to the observing car |
| Self to ball | Relative position and velocity |
| Self to other cars | Relative position and velocity for every other car |
| Goals | Ball displacement to each goal, relative to the observing team |
| Ego | Flip and jump availability, plus remaining dodge-window time |
CARLObservation views
observation.ball.position           # (n_envs, 3)
observation.cars.ego.boost          # (n_envs,)
observation.boost_pad_active        # (n_envs, 34)
observation.ego_ball_relative       # (n_envs, 6)
observation.ego_other_relative      # (n_envs, n_cars - 1, 6)
observation.own_goal_relative       # (n_envs, 3)
observation.ego_has_flip_or_jump    # (n_envs,)
By default CARL normalizes observations via the maximum values of arena extent, velocity, etc. though one may disable this via normalize=False in the environment constructor.
Custom Rewards
Rewards are computed on-device through RewardContext. A reward function receives the previous state and present transition, observations, actions, game events, and episode metadata. It returns one reward per car with shape $(n_{\mathrm{sim}}, n_{\mathrm{cars}})$. Multiple reward functions are summed and multiplied by reward_scale. Registering custom rewards replaces the default score-only reward.
As an example, we can reward based on car velocity (higher-the-better):
import carl

def speed_reward(context):
    return context.current.car_velocity.norm(dim=-1) / carl.CAR_MAX_SPEED

env = CARLTorchVectorEnv(
    n_sim=1024,
    n_blue=1,
    n_orange=1,
    reward_funcs=[speed_reward],
)
An arbitrary list of custom rewards may be applied, though it is usually best practice to unify rewards depending on their requisite context.
Implementation
As stated in the introduction, much of the logic in CARL is redundant with that of RocketSim/Bullet. However, a few alterations were made to make CARL a better fit for execution on the GPU. This section highlights those key differences.
Game State
The game state resides entirely on the GPU in a struct-of-arrays layout. During simulation, the kernels index into these arrays to perform data-dependent computations or modify state information.
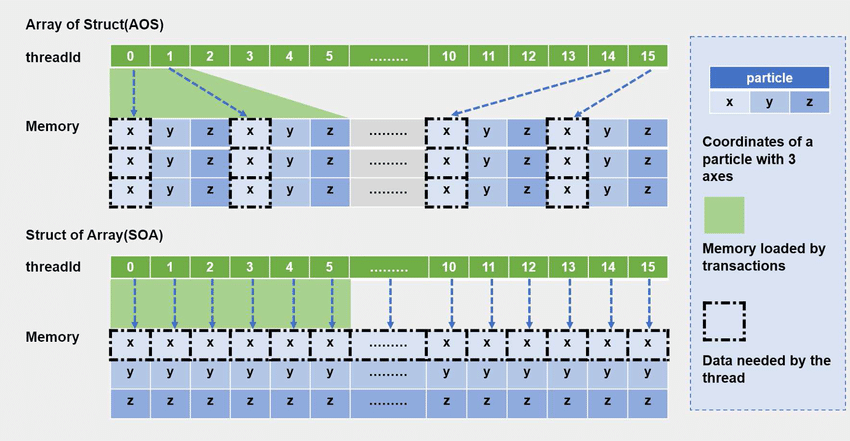
SoA is the optimal approach for data storage in GPU applications due to the enforcement of coalesced fetch instructions for contiguous elements. If we were instead to store arrays of structs, each associated with a single game’s state, the GPU would be forced to perform strided accesses, leading to more memory transactions. We’d also be pulling in full structs worth of data we may not need at the time.
triangles are accessed via CUDA’s cache-optimized read-only load intrinsics.
Arena Geometry
The arena mesh is loaded into global memory upon environment initialization. In contrast to RocketSim’s bounding volume hierarchy (BVH) broad phase [3], CARL divides the arena into a 3D broad phase grid of fixed size. The broad phase helps to reduce the number of triangle tests during collision resolution, and the fixed grid in particular enforces greater regularity of the triangle checks on the GPU.
CARL leverages the prefix sum construction described in NVIDIA’s Broad-Phase Collision Detection with CUDA [6]. The prefix sum converts each broad phase cell’s triangle occupancy into offsets/counts, allowing the car-arena and ball-arena collision kernels to determine where a cell’s triangle list begins and how many triangles it must test.
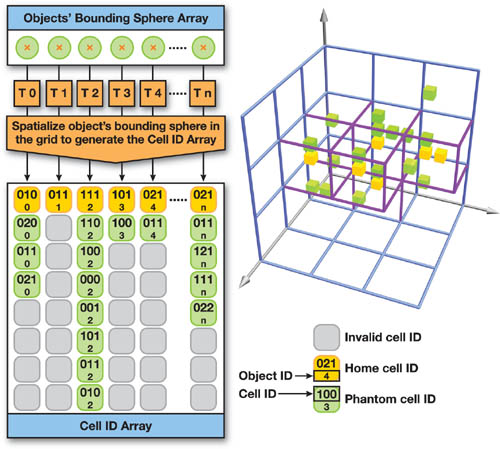
It is quick to check both sphere and axis-aligned bounding box (AABB) occupancy, so we can quickly cull most of the triangles in the arena before checking specific tris against the car and ball.
SAT Narrow Phase
Unlike RocketSim, CARL does not use GJK/EPA [7]. Instead, it implements the Separating Axis Theorem (SAT) [7] to identify car-arena and car-car collisions without iterative support mapping.
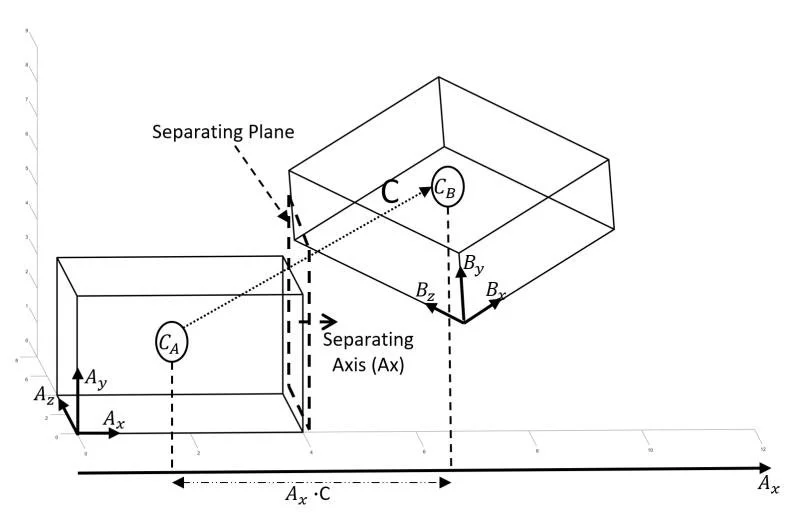
Sphere-OBB and sphere-triangle closest point tests generate car-ball and ball-arena contacts. Clipping via Sutherland-Hodgman [9] constructs the car contact manifolds.
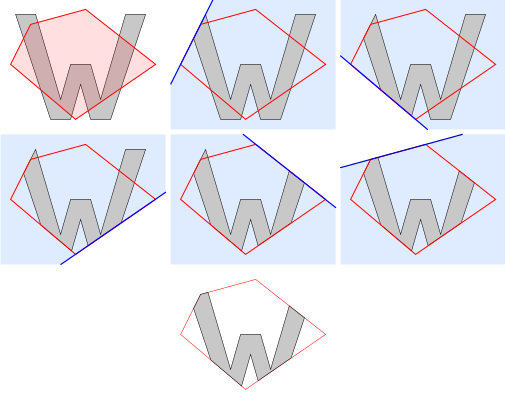

These manifolds are persistent and updated each tick depending on the generation of new contact points. A maximum of 4 points is allowed per manifold in line with RocketSim.
I/O
Below the Gymnasium wrapper, carl.Env is a CUDA-only DLPack interface. [10] Inputs must be contiguous tensors on the device. This way, no host round trip is required.
The native batch is organized by match rather than actor. All cars in a single simulation share one physics world, score, reward event, and termination/truncation flags. The PyTorch wrapper flattens the leading two dimensions so that each car appears as a separate environment.
step() first packs the transition state and terminal observations, then automatically resets completed matches to shuffled kickoffs (or samples from user-specified reset states) and produces the next observation buffers. Returned DLPack tensors are non-owning views over CARL’s reusable GPU buffers, so callers that need to retain a result across a subsequent step() must clone or copy it. The Gymnasium PyTorch wrapper does this by default and expands match-level rewards and terminations back to each participating car.
Conclusion
CARL represents a significant leap in Rocket League RL throughput, and it is my opinion that this is largely a good and valuable thing for the community. Thank you for reading if you made it this far! All love to Mr. Carl Wheezer.
Note: If anyone who is familiar with the RLGym ecosystem finds any fault with the benchmarking methodology, please reach out! I’m confident CARL enables an appreciable training speed-up, but I’d like to ensure all comparisons are appropriate.
References
- NVIDIA. (n.d.). Isaac Lab documentation.
- Lu, C. (n.d.). Meta-discoveries from PureJaxRL [Blog post].
- ZealanL. (n.d.). RocketSim [Computer software]. GitHub.
- Bullet Physics. (n.d.). Bullet Physics SDK [Computer software]. GitHub.
- Zhao, W.-L., Wang, W., and Wang, Q. (2022). Optimization of cosmological N-body simulation with FMM-PM on SIMT accelerators. The Journal of Supercomputing, 78(5), 7186-7205.
- Le Grand, S. (2007). Broad-phase collision detection with CUDA. In H. Nguyen (Ed.), GPU Gems 3 (Chapter 32). Addison-Wesley.
- van den Bergen, G. (2004). Collision detection in interactive 3D environments. Morgan Kaufmann.
- Tayyub, M., and Khan, G. N. (2019). Heterogeneous design and efficient CPU-GPU implementation of collision detection. IADIS International Journal on Computer Science and Information Systems, 14(2), 25-40.
- Sutherland, I. E., and Hodgman, G. W. (1974). Reentrant polygon clipping. Communications of the ACM, 17(1), 32-42.
- DLPack contributors. (n.d.). DLPack documentation.